
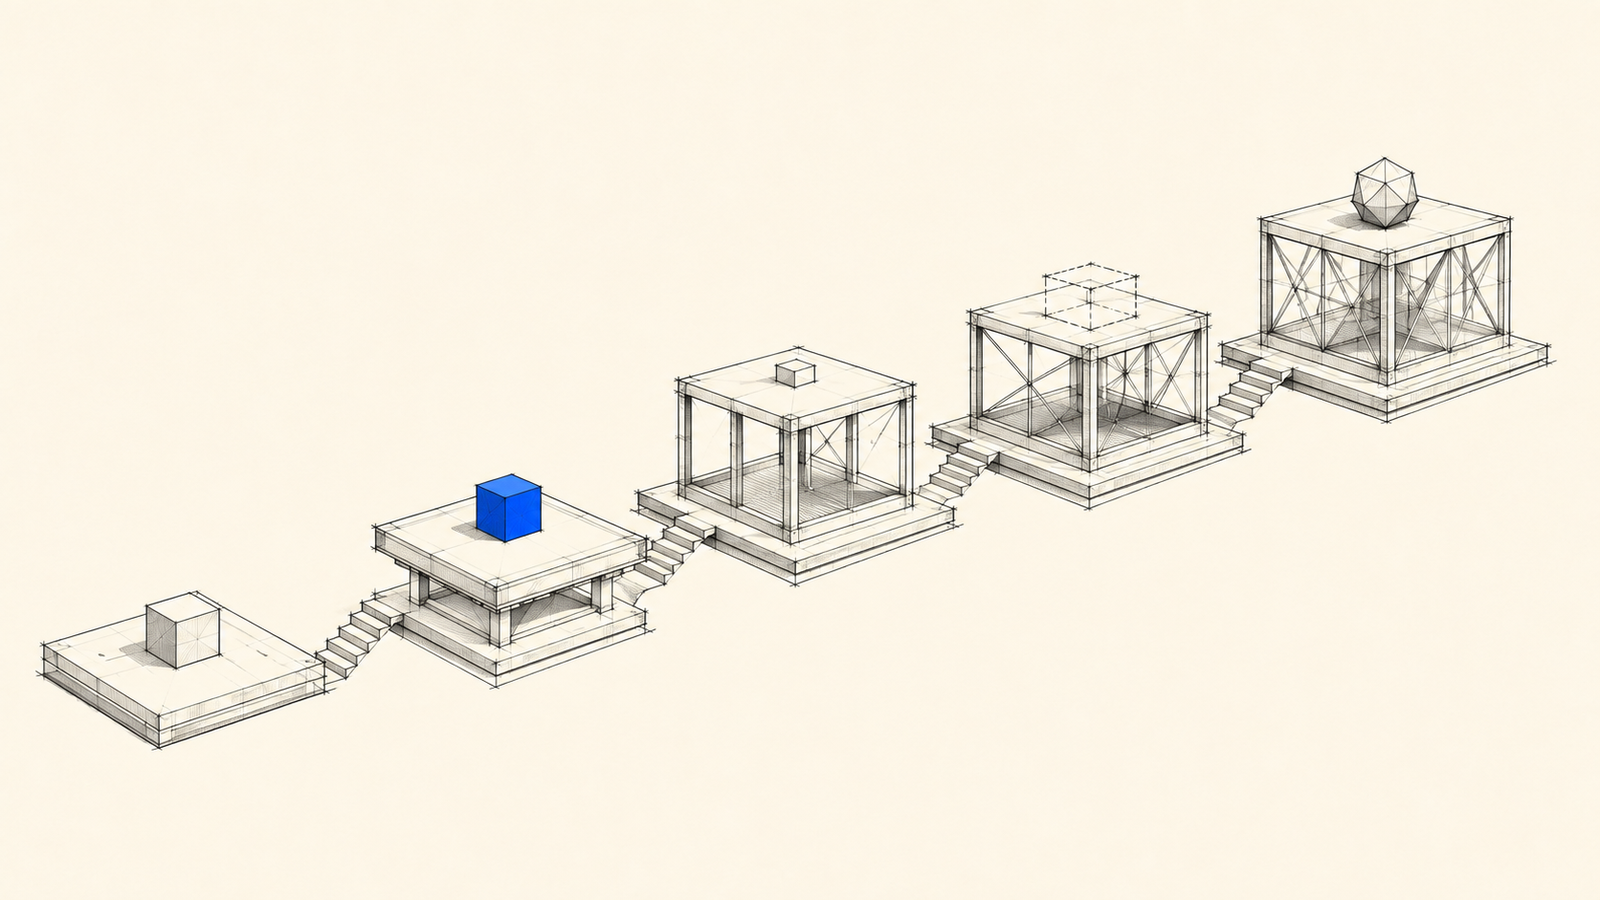
The slide says “AI-native platform.” It has been on the board deck for two quarters. The CTO presented it, the demo went well, and nobody in the room had a reason to doubt it.
Three floors down, an engineer is looking at a handler with an AI vendor’s SDK call in the middle of it. The prompt is a simple string constant. There is no evaluation set, and nobody knows what one request costs.
Both of those things are true at the same time, in the same company, about the same system.
We Have Been Here Before
Cloud maturity models had this exact problem. An organization would run its estate on rented virtual machines, put “cloud” on the roadmap, and grade itself at the top of whatever model the consultant brought in. The gap between the self-assessment and the architecture was two levels, almost every time.
The reason was always the same. The visible surface of a lifted-and-shifted system and a cloud-native one is identical. Same URL, same login page, same features.
The difference is entirely in what happens when load doubles or a zone goes down, and nobody grades on that until it happens.
AI has the same shape. A bolt-on chat feature and an AI-native one look the same in the demo. They differ in what happens when the model is wrong, when usage triples, when a source document changes, and when the vendor ships an update.
Those are the four properties from the first four articles in this series, and they are the only honest basis for a maturity model. So here is a suggested AI maturity model. Five levels, and every level comes with a test you can run this week, rather than an adjective you can claim.
Level 1: Attached
The model is called directly from the code that needed it. The prompt lives in the handler. If you deleted the feature tomorrow, nothing else in the system would notice.
The test is a search. Count the places in your codebase that import a vendor SDK. At level 1 the answer is more than one, and each one was added by whoever needed it that week.
There is nothing wrong with being here. This is where every organization starts, and it is the right place to learn what the technology does. The problem is only ever staying here while telling the board something else.
Level 2: Shipped
Real users touch the feature. There is a prompt in a repository, a monthly bill from the provider, and a demo that works. This is where most enterprises are today, and it is where management’s slide says “AI-native.”
But this is just the start. There are two tests you can apply here. Ask what a single transaction costs in inference, as opposed to what the bill was last month. Then ask who owns the evaluation set.
At level 2 the first answer is a shrug and the second is a name that is followed by “sort of.” The feature works because the model is good, and the team is hoping, without saying so, that it stays that way.
Level 3: Measured
An evaluation test data set exists, drawn from what users actually do. Someone outside engineering agreed to an acceptance threshold. The cost per transaction is a known number that somebody owns.
The test is a question about the past. What did the last model update do to your accuracy, with numbers?
At level 3 the team can answer, because a vendor update became a measurable event rather than a rumor confirmed by customer complaints. Nothing about the architecture has been redesigned yet. The team can simply see and measure what they have.
This is a bigger step than it looks. The eval set is the instrument every later level depends on, and most organizations never build it because the demo already worked. Well, it worked sometimes, anyway.
Level 4: Designed
All four properties have an answer in the architecture of the system that matters most.
There is a verification layer with a written behavior for low confidence. Model selection is a recorded decision with a named owner, and the system routes to the smallest model that clears the requirements bar.
Every context source has a freshness bound and enforces today’s permissions. The model sits behind a boundary, and the harness says what changed when you swap it.
The test is the sixteen questions from the first four articles in this series, asked about one system. Level 4 is most of them answered yes, and the few no’s written down as accepted debt rather than discovered later.
Level 5: Default
Level 4 was about one system. Level 5 is about the organization.
The second AI-heavy system took less architecture work than the first, because the boundary, the harness, and the routing controls already existed. Ownership of evaluation and of the context supply chain is a standing role rather than a person who happened to care.
A design review asks about the four properties the way it asks about availability.
Put the architecture of your newest AI system beside your oldest. If the new one started where the old one finished, you are here. If it started from scratch, you are at level 4 with a good team.
Why Everyone Is Two Levels Off
Level 2 looks like level 4 from the outside. That is the entire problem.
Every signal an executive can see, the demo, the usage numbers, the customer quotes, is identical at both levels. Every signal that separates them, the eval set, the cost per transaction, the freshness bound, the boundary, is invisible until something goes wrong. So the self-assessment tracks the visible signals and lands two levels high.
The uncomfortable part is that the gap has a direction. An organization at level 2 that believes it is at level 4 has stopped doing the work, because the work looks finished. An organization that knows it is at level 2 is still moving.
The Level Test
Take the one system where AI matters most to your business, and grade it, not the company.
Count the vendor SDK call sites. Ask what one transaction costs. Ask who owns the eval set, and what the last model update did to the numbers. Ask whether a new AI system here would start with the last one’s boundary and harness or start from nothing.
Write down the level the evidence supports. Then look at the slide.
Bolt-On or AI-Native
Every enterprise said they were in the cloud. Most had moved the same monolith onto rented servers. Same architecture, same failure modes, new invoice. We called it lift-and-shift, and it took most of a decade to explain why that was a starting point and not a destination.
Bolt-on AI is that same move. Wire a model into a workflow, ship the feature, update the deck.
AI-native is the same answer cloud-native was. Stop hosting the old design on the new platform and design for what the platform actually is. Bolt-on AI grades itself on the demo. AI-native grades itself on what the evidence says about all four properties: probabilistic behavior, inference economics, the context supply chain, and model lifecycle.
The full four-properties test is in the article that started this series.
Next Tuesday: the AI architecture that looks like success and is the distributed monolith all over again.